Category: Technical SEO | SEO Audit | Digital Marketing
Read time: 8 min
Table of Contents
- Why Technical SEO Audits Go Wrong
- Mistake 1: Auditing Everything Instead of Prioritizing Revenue Pages
- Mistake 2: Fixing Symptoms Instead of Root Causes
- Mistake 3: Only Checking the Homepage for Core Web Vitals
- Mistake 4: Treating the Audit as a One-Time Event
- Mistake 5: Blocking AI Crawlers in robots.txt Without Realizing It
- Mistake 6: Routing All 404s to the Homepage
- Mistake 7: Canonical Tags in JavaScript Instead of Static HTML
- Mistake 8: Skipping Log File Analysis
- Mistake 9: Ignoring Index Bloat
- Mistake 10: Missing or Outdated XML Sitemaps
- Mistake 11: Auditing Mobile as an Afterthought
- Mistake 12: Not Validating Structured Data After Site Changes
- The Three Problems a Good Audit Separates
- Bottom Line
Most technical SEO audits produce a long list of issues. However, long lists are not the same as useful audits. The difference between a technical SEO audit that moves rankings and one that keeps a development team busy for weeks without impact comes down to the mistakes made before any fixes are written.
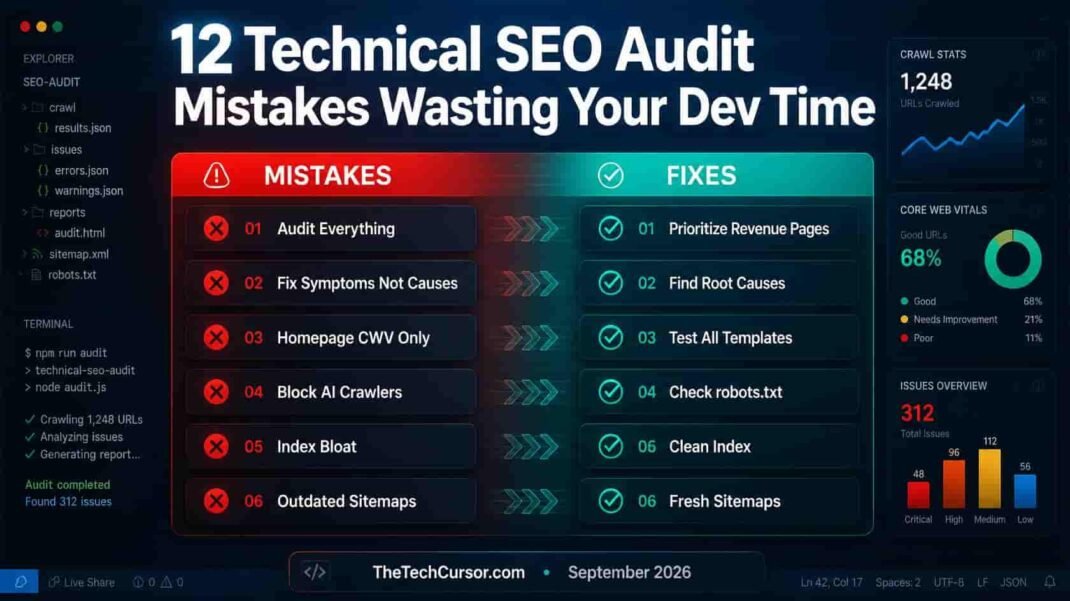
<cite index=”15-1″>Auditing 200 items instead of prioritizing the 20 that move rankings is one of the most common audit mistakes. Most issues have minimal impact. The goal is to focus on what affects revenue-bearing pages first.</cite>
Here are the eight most expensive technical SEO audit mistakes — and what to do instead.
1. Why Technical SEO Audits Go Wrong
The root cause of most bad technical audits is a tool-first approach. An SEO tool runs a crawl, produces a list of flagged issues, and the audit becomes an exercise in working through that list from top to bottom.
The problem is that SEO tools lack context. They flag issues without knowing which pages drive revenue, which issues are intentional, or which problems have already been investigated and deprioritized. As covered in TheTechCursor’s article on technical SEO time-wasters, clearing every warning in your SEO tool is not the goal — improving the performance of pages that matter is.
A good technical audit starts with three questions: Can search engines and AI systems access and understand my most important pages? Are those pages performing well for users? Are the pages I want to rank being chosen over competitors? The tool is an input to those questions — not the audit itself.
2. Mistake 1: Auditing Everything Instead of Prioritizing Revenue Pages
<cite index=”14-1″>Critical issues to fix immediately include Core Web Vitals failures across template-level pages, mobile usability errors flagged in Search Console, crawl errors blocking important pages from indexation, and broken internal links on high-traffic pages. These directly suppress rankings and should be resolved within days, not weeks.</cite>
The most expensive audit mistake is treating every flagged issue with equal urgency. A broken image on a blog post from 2019 and a crawl error blocking your highest-converting product page are not equivalent problems. However, many audits list them adjacent to each other — and development teams fix them in the order they appear.
The fix: Before touching any flagged issue, segment your site by commercial importance. Identify your highest-traffic pages, your highest-converting pages, and your most-linked pages. Fix technical issues on those pages first — in every audit category — before moving to lower-priority content.
Furthermore, distinguish between template-level issues and individual page issues. A Core Web Vitals failure on a page template affects every page using that template simultaneously. Template-level fixes have compounding impact — fixing the template fixes hundreds of pages at once.
3. Mistake 2: Fixing Symptoms Instead of Root Causes
<cite index=”17-1″>Fixing the symptom instead of the cause — redirecting a broken page instead of finding out why it broke — is one of the most common patterns in technical SEO audits.</cite>
A redirect from a broken URL to a live page resolves the immediate crawl error. However, if the page broke because of a template change that will also break the next ten pages published with that template, the redirect fixed one instance of a recurring problem.
Common symptom vs cause pairs:
- Symptom: 20 pages returning 404 — Cause: A site migration that did not preserve URL structure
- Symptom: Canonical tags pointing incorrectly — Cause: A CMS plugin that overwrites canonical tags on certain page types
- Symptom: Core Web Vitals failures on mobile — Cause: Third-party scripts loading synchronously in the page head
- Symptom: Pages “Crawled but not indexed” — Cause: Thin content pattern affecting an entire content category
Root cause analysis adds time to an audit — and it is worth every minute. A fix that addresses the root cause prevents the same issue from appearing in the next audit. A fix that addresses only the symptom creates recurring work.
4. Mistake 3: Only Checking the Homepage for Core Web Vitals
<cite index=”17-1″>A common mistake is only checking the homepage. Test your key pages too — speed often varies page to page.</cite>
PageSpeed Insights on the homepage passes. Everything looks fine. However, the product pages — which use a different template with heavier JavaScript and multiple third-party embeds — fail Core Web Vitals on mobile. The audit misses this entirely because the homepage was the only page tested.
Core Web Vitals scores vary significantly by page template, content type, and device. A news article template with large images above the fold will have different LCP characteristics than a homepage with minimal above-fold imagery. A product page with embedded reviews, size selectors, and gallery components will have different INP characteristics than a static about page.
The fix: Test Core Web Vitals across at least one representative page from each major template type — homepage, category pages, product or service pages, blog posts, and landing pages. Use the Core Web Vitals report in Google Search Console — which shows real-user data across all indexed pages — rather than relying solely on PageSpeed Insights for individual pages.
5. Mistake 4: Treating the Audit as a One-Time Event
<cite index=”15-1″>Treating the audit as a one-time event is a mistake. Technical health drifts. New content is published, template changes are deployed, third-party scripts are added — and each change can introduce new technical issues.</cite>
A technical audit that identifies and fixes every issue today will have new issues by next quarter — because sites change continuously. New pages are published. Plugins are updated. CDN configurations change. Each change creates potential for new technical problems.
The fix: Establish a tiered monitoring cadence rather than treating an audit as a project:
- Weekly: Search Console crawl error and coverage report review — catches new issues within days of introduction
- Monthly: Core Web Vitals trends and manual action check
- Quarterly: Full Screaming Frog crawl — schema markup validation, redirect chain check, internal linking audit
- After every major site change: Targeted audit of the changed templates and affected pages
As covered in TheTechCursor’s article on the SEO blind spot, ongoing measurement is what converts a one-time fix into a durable improvement.
6. Mistake 5: Blocking AI Crawlers in robots.txt Without Realizing It
This is the most 2026-specific audit mistake — and one that is causing significant AI search visibility problems for sites that are entirely unaware of it.
<cite index=”8-1″>Accidentally blocking AI crawlers in robots.txt is one of the most frequent errors found in 2026 technical audits. These errors often prevent sites from appearing in AI-powered search overviews.</cite>
Many sites have legacy robots.txt rules — particularly broad wildcard rules added years ago to block scrapers or content thieves — that inadvertently block the crawlers used by AI search systems. GPTBot (OpenAI), ClaudeBot (Anthropic), PerplexityBot, and Google-Extended all need explicit access to crawl content for AI search consideration.
The fix: Open your robots.txt file and review every User-agent rule. Identify any wildcard rules (User-agent: *) that might block AI crawlers alongside the scrapers they were intended to block. Explicitly allow the major AI crawlers if they are not already permitted:
User-agent: GPTBot
Allow: /

User-agent: ClaudeBot
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: Google-Extended
Allow: /
Furthermore, check your server logs for visits from these user agents. If none appear, your robots.txt is likely blocking them.
7. Mistake 6: Routing All 404s to the Homepage
<cite index=”13-1″>The common mistake is routing all 404s to the homepage — Google treats this as a soft 404 and discounts the redirect entirely, meaning none of the link equity is recovered.</cite>
This appears in audits as a performance-of-intent issue. The site owner or developer believes they are recovering link equity and improving user experience by redirecting broken URLs to the homepage. However, Google recognizes when a redirect destination is topically unrelated to the source URL — and treats it as a soft 404 rather than a meaningful redirect.
The correct priority order for 404s:
- Restore the content if it was removed by mistake
- 301 redirect to the most topically relevant live page if the content was intentionally removed
- Allow the true 404 if there is genuinely no relevant destination — a real 404 is better than a misleading redirect to the homepage
Audit your redirect destinations specifically for homepage redirects from removed content. Identify which of those pages had significant inbound links or traffic. For high-value removed pages with external links, the correct fix is a redirect to the closest topically equivalent live page — not the homepage.
8. Mistake 7: Canonical Tags in JavaScript Instead of Static HTML
<cite index=”13-1″>Two implementation pitfalls recur across audits: canonical tags pointing to a non-HTTPS URL, and canonical tags inserted via client-side JavaScript rather than in the static head of the initial HTML response. Canonical tags belong in static HTML, always pointing to the HTTPS version of the preferred URL.</cite>
JavaScript-rendered canonical tags create a specific problem: Googlebot may process the page before JavaScript executes — meaning it never sees the canonical tag that was supposed to guide its duplicate content handling. The result is that canonicalization intended to consolidate duplicate pages fails silently — and the duplicate content problem it was meant to solve persists undetected.
The fix: Use your browser’s “View Source” function — not the browser inspector — to check whether canonical tags appear in the static HTML. The View Source shows what Googlebot receives on initial page load. If canonical tags are absent from View Source but visible in the inspector, they are JavaScript-rendered and need to be moved to the server-side rendered HTML.
This is particularly common in headless CMS implementations, React-based sites, and WordPress sites using page builder plugins that add canonical tags via client-side JavaScript.
9. Mistake 8: Skipping Log File Analysis
Log file analysis is the most underused technical SEO tool available — and the one that reveals problems that crawl tools and Search Console cannot surface.
<cite index=”13-1″>Regularly monitor how bots behave on your server to spot crawling inefficiencies before they impact your traffic. Log file analysis reveals which pages Googlebot actually visits, how frequently it visits them, and whether its crawl patterns match the site’s priority architecture.</cite>
Without log file analysis, you cannot know:
- Whether Googlebot is spending crawl budget on low-priority pages while missing high-priority ones
- Whether AI crawlers are accessing your site at all — or being blocked
- Whether specific server responses are causing Googlebot to stop crawling certain sections of the site
- Whether your crawl rate has changed following algorithm updates or site changes
The fix: Request server log access from your hosting provider or infrastructure team. Parse logs for Googlebot, GPTBot, ClaudeBot, and PerplexityBot visits. Map crawl activity against your priority page architecture — pages Google visits frequently should be your most important pages. Where they diverge, investigate the cause.
For enterprise sites, dedicated log analysis tools like Screaming Frog Log Analyzer, Botify, or Oncrawl make this process significantly more practical at scale.
10. Mistake 9: Ignoring Index Bloat
Index bloat is one of the most commonly overlooked technical SEO problems — and one of the most expensive for large sites. It occurs when Google has indexed significantly more pages than a site actually has valuable content for — typically due to URL parameter variations, faceted navigation, tag pages, or thin auto-generated content.
(cite index=”8-1″>Struggling with index bloat is one of the most common issues in 2026 technical audits. Sites with index bloat force Google to spend crawl budget on low-value pages — reducing how frequently Googlebot visits high-value pages and diluting the overall quality signal the site sends.</cite>
A site with 10,000 indexed pages but only 1,000 pages with genuine search value is sending a diluted quality signal across all of them. Furthermore, as covered in TheTechCursor’s content pruning guide, pages that exist primarily to satisfy internal navigation rather than genuine search demand can actively suppress the topical authority of the pages that do matter.
The fix: Pull your total indexed page count from Google Search Console’s Page Indexing report. Compare it against your intentionally published content inventory. A significant gap — particularly on e-commerce sites with faceted navigation or content sites with large tag page archives — signals index bloat.
Address index bloat through a combination of: noindexing thin tag and category pages, implementing canonical tags for parameter-generated duplicate URLs, blocking faceted navigation parameters in robots.txt or Google Search Console URL parameters settings, and using the <meta name="robots" content="noindex"> tag on genuinely thin auto-generated pages.
11. Mistake 10: Missing or Outdated XML Sitemaps
XML sitemaps are one of the simplest technical SEO components — and one of the most frequently neglected. An outdated sitemap that still references deleted URLs, or a missing sitemap for a large section of the site, directly reduces Google’s discovery efficiency for new and updated content.
(cite index=”17-1″>Forgetting to update the sitemap after a redesign is a common mistake. After a site migration or structural change, sitemaps frequently contain references to URLs that no longer exist — creating a misleading picture of the site’s current state for Googlebot.</cite>
Furthermore, sitemaps should only reference canonical, indexable pages — not pages with noindex tags, pages blocked in robots.txt, or redirect URLs. A sitemap that includes these creates confusion about which URLs Google should treat as authoritative.
Common sitemap mistakes to audit for:
- Sitemap contains URLs returning 404 or 301 redirect status
- Sitemap includes pages with noindex tags
- Sitemap has not been updated after a site migration or URL restructure
- Sitemap is not submitted in Google Search Console
- Large sections of the site — such as a new blog or product category — are absent from any sitemap
The fix: Crawl your sitemap URLs with Screaming Frog or a similar tool to identify non-200 responses. Remove all redirecting and error URLs. Ensure all high-value page types are represented. Resubmit the updated sitemap in Google Search Console and monitor the Coverage report for sitemap-specific indexation improvements.
12. Mistake 11: Auditing Mobile as an Afterthought
With the majority of Google searches now occurring on mobile devices, mobile performance is not a secondary audit consideration. However, many technical SEO audits still lead with desktop analysis and treat mobile as a validation step — checking that the desktop experience also works on mobile rather than treating mobile as the primary surface to optimize for.
(cite index=”17-1″>Skipping mobile checks because the desktop site looks fine is a common audit mistake. Text that is too small to read, buttons or links placed too close together, and content that does not fit the screen without scrolling sideways are all mobile usability issues that directly affect rankings — and that are invisible when auditing only from a desktop browser.</cite>
Furthermore, Core Web Vitals scores frequently differ significantly between desktop and mobile. A site that passes LCP on desktop may fail on mobile due to different image loading behaviour, different above-the-fold content, or mobile-specific render-blocking resources.
Mobile-specific checks to include in every audit:
- Core Web Vitals: Pull mobile-specific data from the Core Web Vitals report in Google Search Console — not just PageSpeed Insights desktop scores
- Mobile Usability report: Check Google Search Console’s Mobile Usability report for specific flagged issues across all indexed pages
- Text readability: Verify font sizes are at minimum 16px on mobile, and that tap targets are at least 48×48 pixels
- Viewport configuration: Confirm the viewport meta tag is correctly set on all page templates
- Mobile-first indexing: Google uses the mobile version of your content for indexing. Verify that content on mobile is not truncated or hidden behind interactions that Googlebot cannot replicate
13. Mistake 12: Not Validating Structured Data After Site Changes
Structured data implementation is validated once during initial setup — and then frequently forgotten. The problem is that structured data errors are introduced continuously: template updates break schema markup, CMS plugin updates overwrite existing implementations, and page content changes invalidate previously accurate structured data values.
(cite index=”13-1″>Schema markup errors introduced by template updates are among the most common issues found in quarterly Screaming Frog crawls. A template change that removes a required field from Article schema — such as datePublished or author — silently disables rich result eligibility for every page using that template.</cite>
For AI search specifically, structured data is among the most direct signals AI systems can use to understand page content and author credentials — as covered in TheTechCursor’s E-E-A-T 2026 guide and international SEO E-E-A-T article. Schema markup errors that eliminate author entity connections or publication date signals have AI search visibility implications beyond their impact on rich results eligibility.
The fix: Run Google’s Rich Results Test on representative pages from each major template type after any template update or CMS change. Set up a post-deployment validation checklist that includes schema validation alongside performance testing. Furthermore, monitor the Rich Results report in Google Search Console — it surfaces schema errors across your entire indexed site, not just the pages you think to test manually.
Priority schema types to validate after every site change:
- Article/BlogPosting — author, datePublished, dateModified, headline
- Product — name, price, availability, reviews
- LocalBusiness — name, address, phone, hours
- FAQPage — question and answer pairs
- BreadcrumbList — position and item values
14. The Three Problems a Good Audit Separates
Before any technical audit begins, establishing the right framework prevents the most common mistakes from occurring.
<cite index=”12-1″>A strong audit separates three distinct problem types early, because each one produces different fixes, different timelines, and different expectations. A visibility problem means Google cannot crawl or index the right pages. An interpretation problem means Google crawls but renders or understands the page inconsistently. A priority problem means Google understands the site but chooses other pages or other sites as better answers.</cite>
Visibility problems — crawl blocks, indexation errors, robots.txt issues — require technical fixes and are typically resolved quickly.
Interpretation problems — JavaScript rendering failures, canonical tag issues, schema markup errors — require developer involvement and may take longer to propagate through Google’s index after fixing.
Priority problems — Google understands your pages but ranks competitors above you — are content and authority problems, not technical problems. Technical fixes do not solve priority problems. Applying technical remediation to a priority problem wastes developer time and sets incorrect expectations.
Establishing which problem type you are dealing with before writing any recommendations separates audits that drive outcomes from audits that produce lengthy reports with limited impact.
11. Bottom Line
Technical SEO audits are most valuable when they identify the right problems — not the most problems. The 12 mistakes covered here consistently waste developer time, obscure genuine issues, and delay the fixes that actually affect rankings and revenue.
Start with priority segmentation — identify your most important pages before running any tool. Distinguish symptoms from causes. Test Core Web Vitals across all major templates. Check AI crawler access in robots.txt. Fix 404s with topically relevant redirects. Ensure canonical tags are in static HTML. Add log file analysis to your monitoring cadence. Fix index bloat. Maintain accurate XML sitemaps. Treat mobile as primary. Validate structured data after every site change. And establish a recurring review process rather than treating the audit as a one-time project.
The technical issues that move rankings are rarely the ones at the top of an automated tool report. They are the ones found by auditors who start from the right questions — and know which tool outputs to trust and which to question.
Pingback: Before You Hire an SEO Auditor: What You're Actually Paying For in 2026 - The Tech Cursor
Pingback: Google "Couldn't Fetch" Sitemap Errors: Not Always Technical - The Tech Cursor
Pingback: The Business Case for SEO Is Changing: Justify Your Budget - The Tech Cursor